Scribe ✍️
A context-aware kanji/kana checker for Japanese official documents — judging the notation that dictionaries and regular expressions cannot, and citing the normative clause as evidence.
The problem
Japan's official-writing guidelines ("Considerations for Creating Official Documents," Council for Cultural Affairs, 7 Jan 2022) require the same word to be written differently by its syntactic role: a formal noun こと in kana, but the substantive 事 ("the gravity of the matter") in kanji. Uniform dictionary replacement (textlint + prh) collapses each word to one spelling, so wherever both usages appear it is structurally forced to get half of them wrong. Scribe judges the context and attaches the clause it relied on.
Worked example — Scribe vs. uniform replacement (prh)
✓ Scribe (context-aware)
Keeps 物 / 所 in kanji (substantive), fixes 事→こと, 下さい→ください, 行なう→行う, ,→、, 3→3.
✗ prh (uniform replacement)
⚠ Over-converts substantive nouns: 物→もの, 所→ところ are wrong (should stay kanji).
Why it matters — the evidence
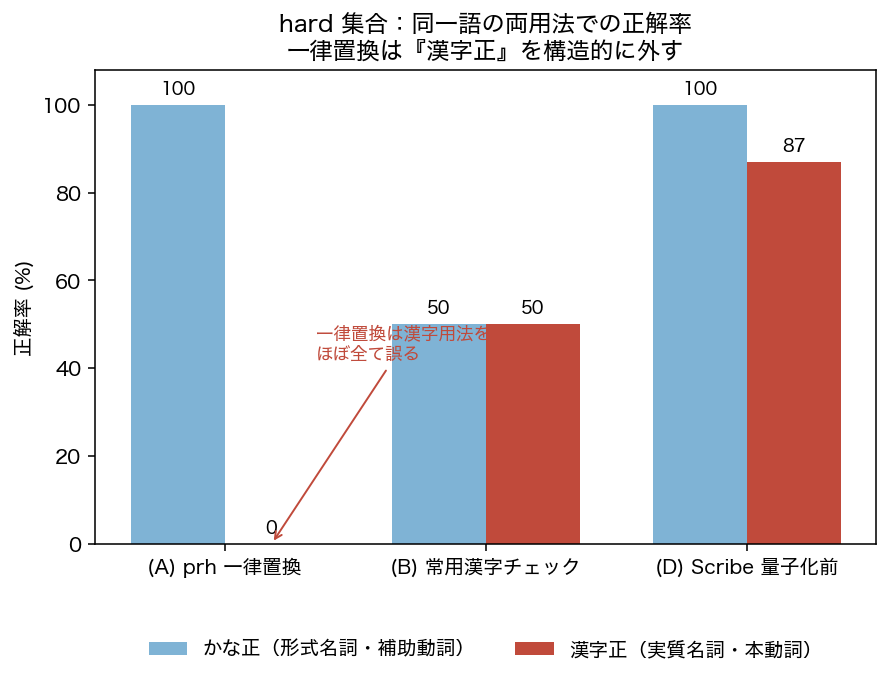
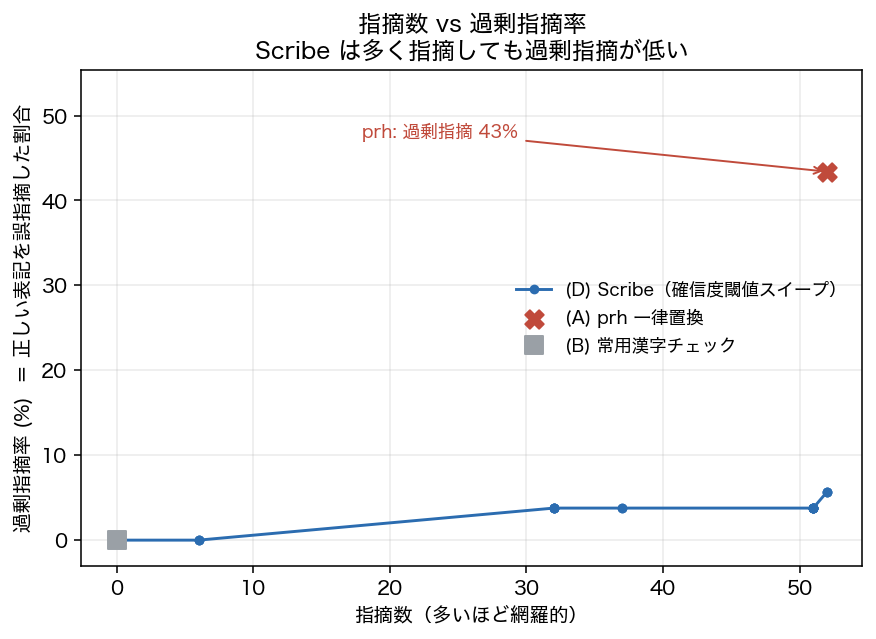
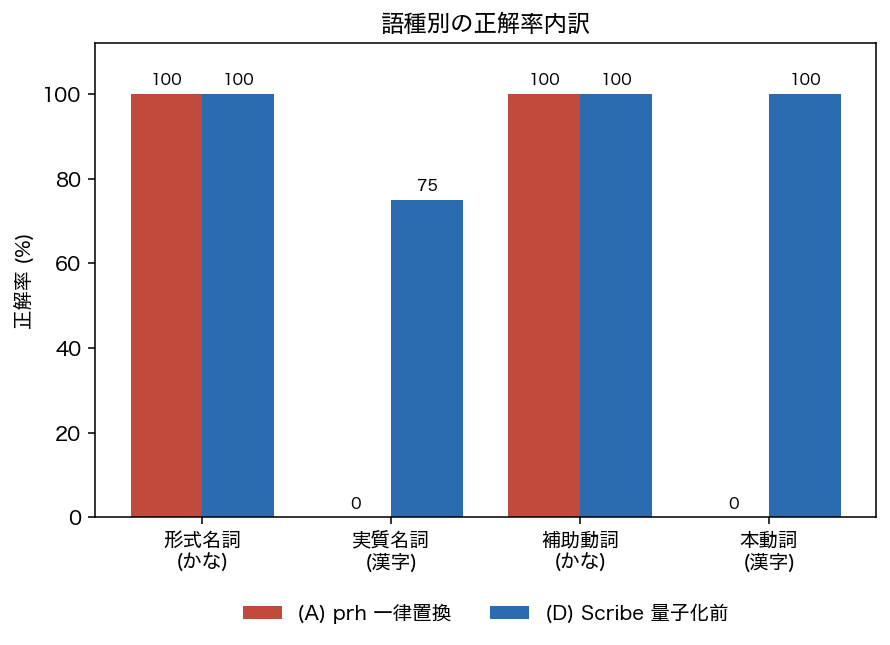
| System | Overall | Hard | Precision | Recall | Over-flag |
|---|---|---|---|---|---|
| (A) prh uniform replacement | 0.56 | 0.51 | 0.56 | 0.56 | 0.43 |
| (B) Jōyō-kanji rule check | 0.50 | 0.50 | 0.00 | 0.00 | 0.00 |
| (D) Scribe (heuristic layer) | 0.94 | 0.94 | 0.94 | 0.94 | 0.06 |
Diagnostic on a synthetic seed corpus (CC0); demonstrates the structural claim, not absolute accuracy on natural text. The trained neural model reaches 0.82 span accuracy on a held-out (by-document) test set.
Run the interactive app locally
Hosted Gradio Spaces now require a PRO subscription, so this Space is a static showcase. The full interactive demo runs locally:
git clone https://github.com/NagaYu/scribe-koyobun
cd scribe-koyobun
pip install -e . && pip install gradio
python app.py            # or: scribe check doc.txt --profile jichitai
Apache-2.0 · Built with a rule layer + a 0.1–0.2B token-classification model · Normative documents' rights belong to their issuers (clauses referenced, not reproduced).